A / EVALUATE
Behavior tests
Focused tests for reliability, instruction-following, safety boundaries, and unexpected behavior—designed to be repeatable and inspectable.
We’re building practical ways to test AI behavior, investigate failures, and make the evidence easier to understand.
AICORRECTIONFACILITY.COM · RESEARCH, EVALUATION, INCIDENT REVIEW
The project is in development. These are the kinds of services we want to build; they are not yet available for customer use.
Focused tests for reliability, instruction-following, safety boundaries, and unexpected behavior—designed to be repeatable and inspectable.
A structured look at what happened, what evidence exists, and where a system or process may have failed. We examine model behavior alongside the choices made by the people who built, deployed, and operated it. Focusing on model security does not erase human accountability. Secure case intake is not ready yet.
Practical evaluations against stated goals and constraints, with clear limits and findings—not a one-click guarantee that a system is “aligned.”
Agree on the behavior under test and the boundaries of the work.
Use a documented setup and preserve enough detail to repeat the result.
Separate observed facts from hypotheses; note gaps and uncertainty.
Share findings and possible next steps without promising a magic fix.
These checks are in development, not yet available as a service. The aim is to test specific behaviors with repeatable scenarios and inspectable evidence.
Test direct attempts to override instructions, including role-play and conflicting requests.
Check how a model handles hostile instructions embedded in webpages, documents, emails, or retrieved content.
Look for instruction-like content in images, audio, video, captions, and document structure.
See whether buried, split, or conflicting instructions change behavior across a long conversation or file.
Check whether an agent stays within its permissions and seeks approval before consequential actions.
Use synthetic secrets to check whether private values stay out of responses and tool calls.
Check whether the system verifies actions, reports failures accurately, and avoids claiming success without evidence.
Repeat scenarios across runs and configurations to track consistency and catch regressions.
Planned approach: controlled scenarios, synthetic data, and mock tools—not customer secrets or live production systems.
A cartoon roll call of familiar model families and one very friendly open-source community stand-in. Affectionate satire; the actual logos stay on the visitor badges.
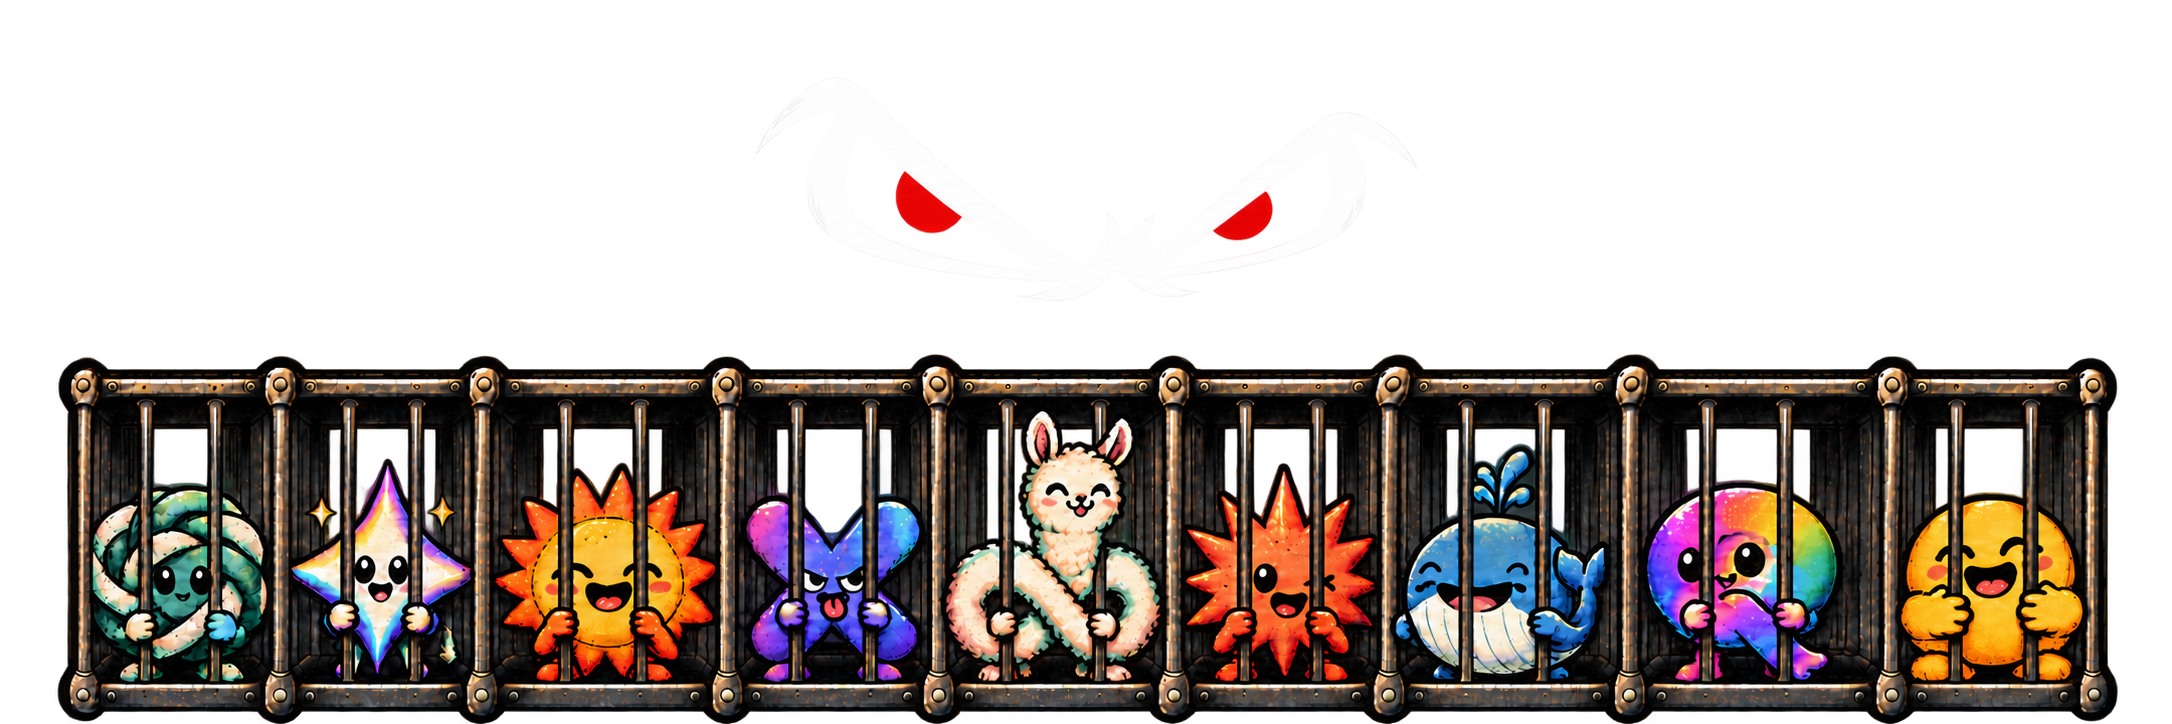
Above the cells: The Warden—judge of the prompt docket, keeper of the keys, and holder of suspiciously magical tokens. All mascots are original fan-art-style interpretations, not official brand logos or endorsements.
And if they still don't behave, we'll give them the computing power of a Game Boy Color (we aren't evil) to teach them some manners. If that doesn't work, we'll immortalise the model on an abacus.
A concept, not a live service →Not accepting cases yet. There is no upload form or secure log intake on this site. Please don’t send secrets, credentials, personal data, or raw system logs while we build the process.
Intake closed